// For AI & automation programmes
AI automation analysts, at scale.
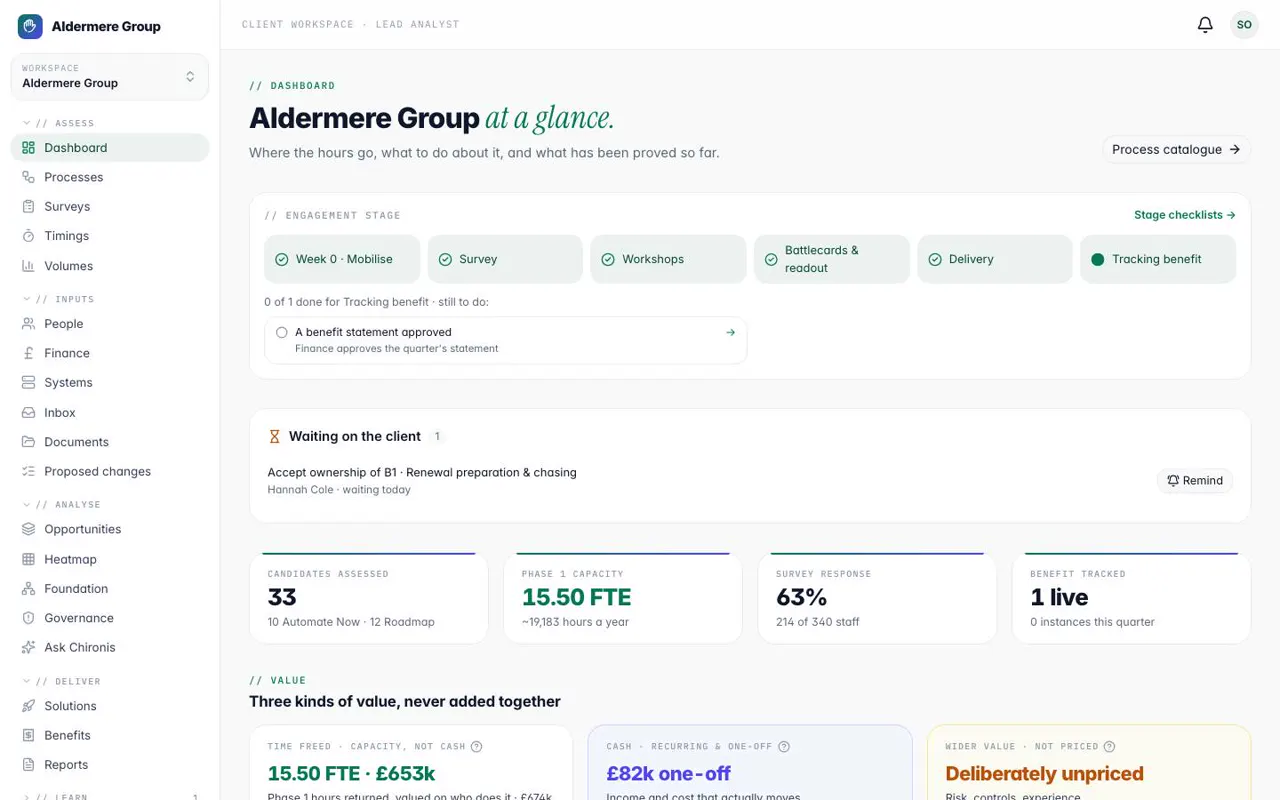
Chironis does the heavy lifting of process analysis across your whole organisation: it runs the interviews, drafts every process map, sizes where AI pays with graded evidence and counts what each automation gives back. Our engineer brings the judgement, starting with a four-week, fixed-fee roadmap assessment.
- Hosted on AWS in London
- Every figure graded
- Salaries never reach an AI
// The situation
AI programmes stall for want of context
The work isn’t written down
Workshops hear from a dozen people. Hundreds do the work, and the quiet processes never make it into the room.
The numbers are asserted
Business cases rest on estimates nobody can trace back to who said what, or how sure anyone was.
Built isn’t delivered
An agent goes live and nobody counts what it gave back, or what happens when it gets something wrong.
Chironis closes all three gaps: an engineer who stays with your teams, and a platform that keeps the evidence.
// How it works
One loop, five stages
Listen, size, assess, build and prove in one place, so the evidence, the business case and the benefit record never disagree.
Listen
Every team, analysed in parallel.
AI interviews, workshop recordings and a staff survey feed one evidence base.
Size
Every number shows its working.
Hours, FTE and value worked out the same way every time, and every figure graded.
Assess
What AI can do here, and what if it’s wrong.
Each task matched to the kind of AI work it needs, then given an error-risk band.
Build
Agents earn their autonomy.
A signed agent card, a test set and a go-live bar before anything runs alone.
Prove
Every case is counted.
A signed baseline, a record of every case and a statement every quarter.
Your engineer judges. Chironis does the heavy lifting. You keep everything.
// 01 · Listen
Three levels of listening
Level 1
Your recordings
Upload Teams or Zoom workshops. Chironis transcribes them, reads the screens and drafts the process map.
Level 2
AI interviews
Fifteen to thirty minutes by voice, from a link. People share their screen or drop in documents; there’s no interviewer to schedule.
Level 3
Work capture
A desktop recorder sees how the work is really done and uploads to your own storage. The person reviews it first. No audio, keystrokes or video.
And a short survey for everyone, broken down only for groups of five or more.
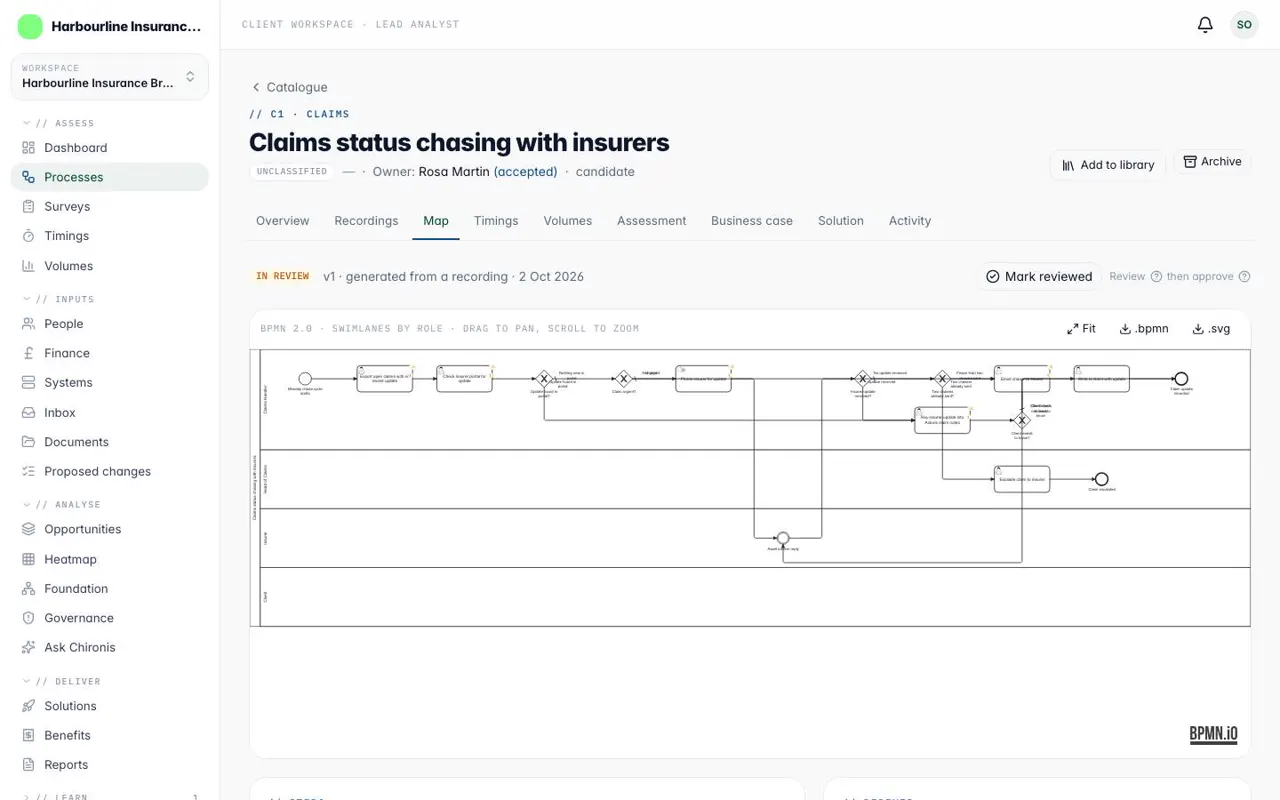
From what people said to an approved map
01 · Heard
Recordings, interviews and captures, every word kept with who said it.
02 · Drafted
A process map with every step linked to the moment it was described.
03 · Approved
The process owner signs it off. Nothing counts until they do.
04 · Written up
An SOP in Word or PDF, read straight off the approved map.
Open standards
Maps export as BPMN 2.0 and open in Camunda or Signavio.
Duplication found
Five detectors flag the same work being done twice across teams.
// 02 · Size
Every number shows its working
The arithmetic
hours   = transactions × minutes ÷ 60
FTE     = hours ÷ productive hours
value   = FTE × % automatable × loaded cost
payback = build cost ÷ monthly value
Pay is valued by role band, never by person, and salaries never reach an AI.
Every figure carries a grade
| Grade | Confidence |
|---|---|
| Observed | ±10% |
| Sampled | ±25% |
| Surveyed | ±25% |
| Estimated | ±30–50% |
| Asserted | Shown, never counted |
Three kinds of value, time freed, cash and wider value, are never added together.
// The rule we never break
Capacity is never reported as cash.
Time freed becomes cash only when it is redeployed or a role isn’t refilled. Until then it is shown as capacity, with its grade beside it, and nobody’s board pack says otherwise.
// 03 · Assess
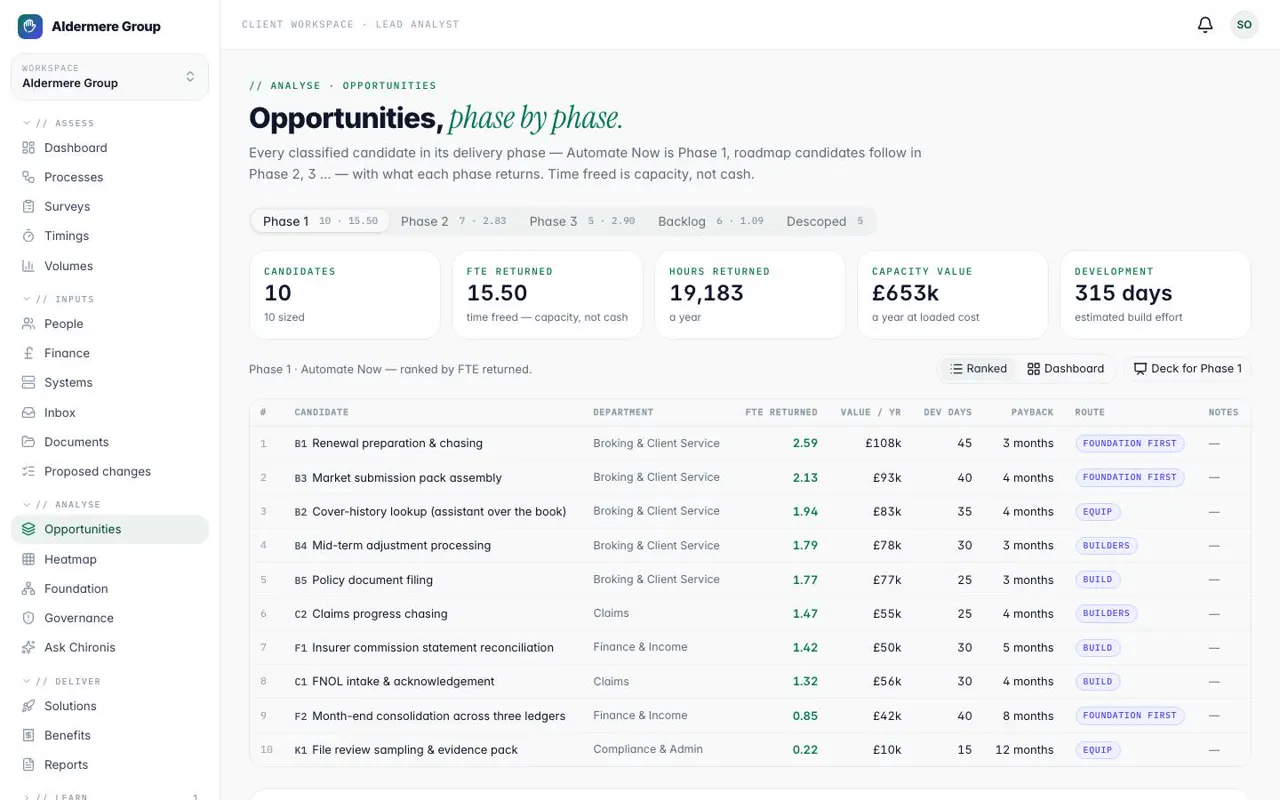
What AI can do here, and if it’s wrong
24
kinds of AI work in seven families, each rated for OpenAI, Claude and Gemini.
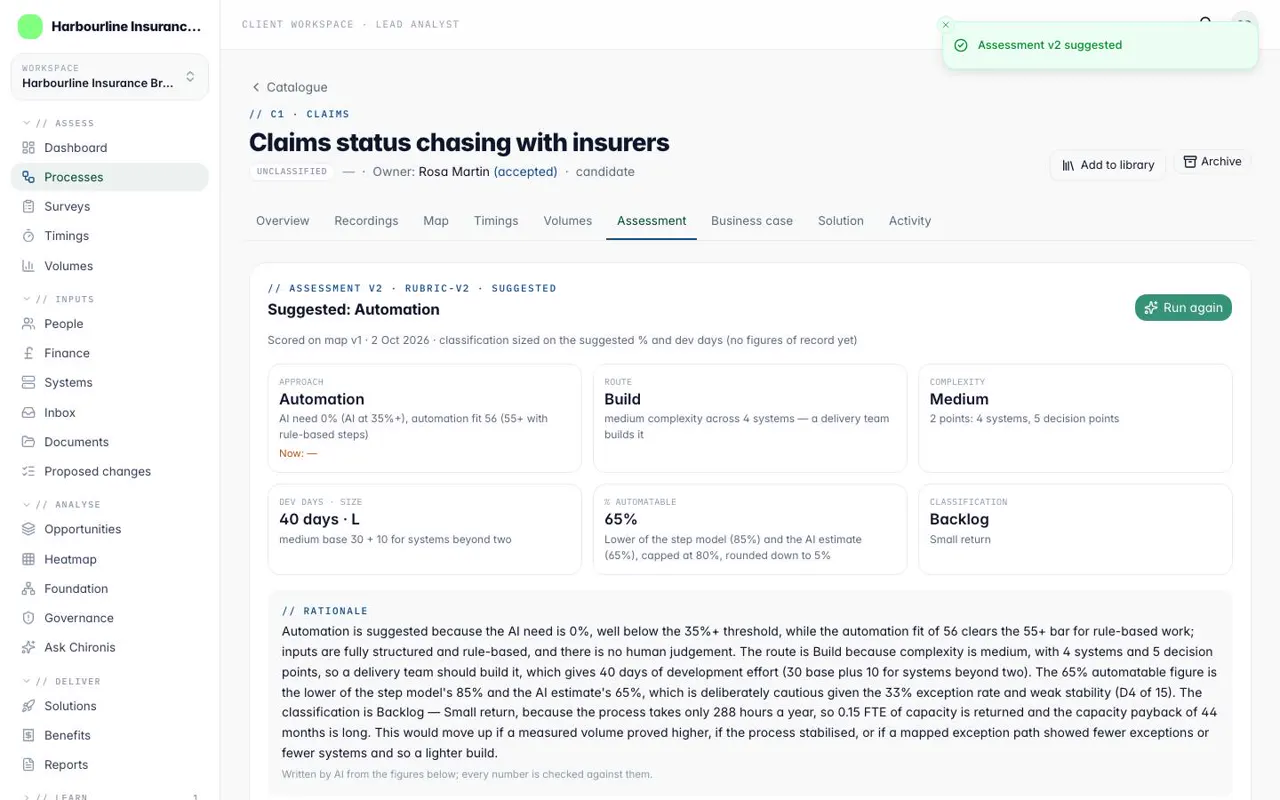
Default error rates are marked Estimated until your own tests replace them.
Error risk sets the ceiling
| Risk band | Most autonomy allowed | Error limit |
|---|---|---|
| Low | Runs on its own | 5% |
| Medium | A person approves flagged cases | 2% |
| High | A person approves each case | 1% |
| Critical | Drafts only | None |
A decision about a person is never rated below High. The expected cost of errors sits beside the benefit, never subtracted from it.
// 04 · Build
Agents earn their autonomy
Request
“What do you need done?” Raised by your team, triaged by the engineer.
Agent card
Drafted from the assessment and signed by you.
Test set
Run in Chironis, or wherever the agent is built.
Go-live bar
Errors under the band’s limit, proved on 150 clean cases.
Live
Monitored, and every incident becomes a new test.
Up a rung only on clean live cases and your approval. Down automatically when errors rise, or when the model, prompt or tools change.
Agents can be built anywhere (Claude Agent SDK, OpenAI Agents SDK, Google ADK, Power Automate, n8n) and report every case to Chironis.
// 05 · Prove
Built isn’t delivered. Every case is counted.
- 01
A baseline first
Measured before anything changes, so the comparison is fair.
- 02
One event per case
Each automation reports every case into a hash-chained, append-only record. Your IT lead holds the keys.
- 03
Six conditions
A case counts as verified benefit only when all six hold.
- 04
A statement every quarter
Line by line, open to dispute, capped as agreed.
The board pack
- Findings report (PDF)
- Deck (PowerPoint)
- Workbook with live formulas
- Process maps (BPMN)
- SOPs (Word, PDF)
- Benefit statements
Everything comes out of the same record, so the deck, the workbook and the business case never disagree.
// Trust
Built to be trusted with how you work
Hosted in the UK
AWS London. Every client in its own walled workspace.
Locked at the database
Row-level security on every client table, tested on every build.
Your recordings, your storage
The desktop recorder uploads straight to your own AWS or Azure account.
Salaries never reach an AI
Pay is encrypted, seen by Finance only and valued by role band.
AI proposes, people decide
Assistants only suggest changes; a person applies them. Every action lands in an append-only audit log.
Capture with care
No audio, keystrokes or video. Field names, never their values. Never used to manage performance.
Built on AWS
Chironis runs in AWS London (eu-west-2) on ECS Fargate, RDS for PostgreSQL, S3, KMS, WAF, SES and CloudTrail, provisioned with Terraform. Each client’s data is isolated in the database itself, and the database and files are encrypted with keys held in KMS.
On the way: single sign-on, UK-only AI processing, SOC 2 and ISO 27001.
// The engagement
Assess, build, run: you decide at every gate
Assess · 4 weeks, fixed fee
Find where AI pays
One forward-deployed engineer runs the roadmap assessment on Chironis.
You get
Sized, graded candidates, a 100-day plan and a costed proposal.
You decide
What to build first, if anything.
Build · 6 weeks to 6 months
Ship what clears the bar
An engineer per area of the business, with developers and AI evaluation engineers behind them.
You get
Agents through the go-live bar, and the evidence they cleared it.
You decide
Every step up in autonomy.
Run · ongoing
Keep the benefit honest
Your engineer stays two or three days a week; Chironis counts every case.
You get
A benefit statement every quarter.
You decide
What comes next on the roadmap.